Classification Persistence
Overview
- Persistent classification is vital for consistent data management
- Data at rest and data at motion both require classification persistence
- archTIS Spirion persistently classifies data at rest using privacy-grade accuracy to label files with metadata which then informs in-motion data loss prevention (DLP) controls.
- Whether applied manually or automatically via Scan Playbooks, classification labels are critical components to protecting sensitive information.
- Using persistent archTIS Spirion-applied labels, DLP solutions focus on performing actions rather than inspecting content, acclerating accuracy and performance
For a high-level video overview of file Classification, Persistence and how it dovetails with data loss prevention tools (DLPs) watch this archTIS Spirion Classification Demo.
What is File Classification Persistence?
File classification persistence refers to the ability of a file's security classification (for example, "Confidential," "PII," "Internal") to remain with the file, regardless of how or where it is moved, copied, renamed, or attached to an email.
This ensures that the classification travels with the data.
What are the Different Types of Classification Persistence?
There are three different types of sensitive data classification persistence:
- Persistent
- Semi-persistent
- Non-persistent
Persistent Classification (Database + File Metadata/Tagging)
In persistent classification, classifications are embedded within the file metadata ensuring the classification persists even when the file is moved, emailed, or copied.
- What it does: The classification is recorded in the Spirion Database AND written directly into the file's metadata/system attributes.
- How it works: The Spirion Agent modifies the target file to embed Spirion classification tags (including the Classification Name and unique GUID). Downstream tools (such as DLP, CASB, firewalls, and EDR agents) can read these tags independently.
- Where the metadata is stored by file type:
- Microsoft Office 2007+ (
.docx,.xlsx,.pptx): Stored inside the custom document properties XML (docProps/custom.xml). - PDF Documents (
.pdf): Stored in the PDF Document Information dictionary and XMP metadata stream. - Images (
.jpg,.png,.tif): Stored in standard XMP / EXIF metadata fields. - Generic Windows Files/NTFS: Stored in an NTFS Alternate Data Stream (ADS) attached to the file without altering the primary data stream.
- Microsoft Office 2007+ (
Semi-persistent
What is Semi-Persistent Classification?
Semi-persistent classification is a method where Spirion writes classification metadata directly to an NTFS Alternate Data Stream (ADS) attached to the file as a "sidecar," rather than embedding it inside the file's internal XML/binary content.
How Semi-Persistent Classification Works
- NTFS Sidecar Storage:
- When an agent classifies a file on a Windows NTFS filesystem (or SMB shares backed by Samba
streams_xattr), it creates a hidden alternate stream attached to the target file. - The file’s primary data stream (and its internal structure) remains untouched.
- When an agent classifies a file on a Windows NTFS filesystem (or SMB shares backed by Samba
- Metadata Stored in the ADS:
Spirion writes specific metadata properties into the stream, primarily: IFClassification_name: The human-readable classification label(s) (e.g.,Confidential,CUI,Finance).IFClassification: The unique classification GUID(s) assigned by the Spirion console.
- Universal File-Format Support on NTFS:
- While fully persistent classification is limited to specific formats (e.g., Office XML
.docx/.xlsx), semi-persistent classification works on any file type residing on an NTFS volume (including plain text files, source code, archives, legacy binaries, and signed PDFs).
- While fully persistent classification is limited to specific formats (e.g., Office XML
Why It is Called "Semi-Persistent" (Boundary Limitations)
The classification is called semi-persistent because its persistence is bound to the underlying filesystem:
- Persists When: The file is renamed, modified, or moved/copied to another directory or volume on an NTFS-formatted drive.
- Stripped When:
- The file is attached and sent via email (SMTP).
- The file is uploaded to cloud storage or web services via HTTP/S (unless explicitly preserved by specialized connectors).
- The file is transferred to a non-NTFS filesystem (for example, FAT32, exFAT, standard Linux ext4/NFS without ADS support).
Comparison of the Three Classification Types
Classification Type | Where Stored | File Format Compatibility | Persists Off NTFS / In Email? |
|---|---|---|---|
Persistent | Embedded directly inside the file metadata (Office XML | Limited to supported formats ( | Yes (Travels with the file everywhere) |
Semi-Persistent | NTFS Alternate Data Stream (ADS) sidecar | All file types on NTFS storage | ❌ No (Stripped if transferred off NTFS) |
Non-Persistent (Database Only) | Spirion database / SaaS persistence layer only; file is untouched | All files, databases, and targets | ❌ No (Visible only within Spirion) |
Database-Only Classification (Logical/Non-Persistent)
In non-persistent classification, classification is retained only within the Spirion application.
- What it does: The classification is recorded only within the Spirion Database/Console Catalog. The physical file on the storage endpoint is not modified.
- How it works: When a scan discovers sensitive data matching a policy, the agent reports the finding up to the console. The database links the file’s path, hash, and metadata with the assigned classification GUID/taxonomy.
- When to use it:
- Read-only shares, immutable archives, or targets where the scanner does not have write/modify permissions.
- Environments where changing file hashes, modification timestamps, or metadata is prohibited by compliance or forensic policies.
- Cloud/SaaS targets where in-place metadata rewriting is disabled or unsupported.
SDM Note: Called “In database” for Spirion Sensitive Data Manager (SDM).
Where is Classification Persistence Set/Applied?
Classification persistence is can be configured or applied from Spirion Sensitive Data Platform in 3 locations:
- Scans Settings - Set before scans run
- Scan Playbooks - Set before scans run
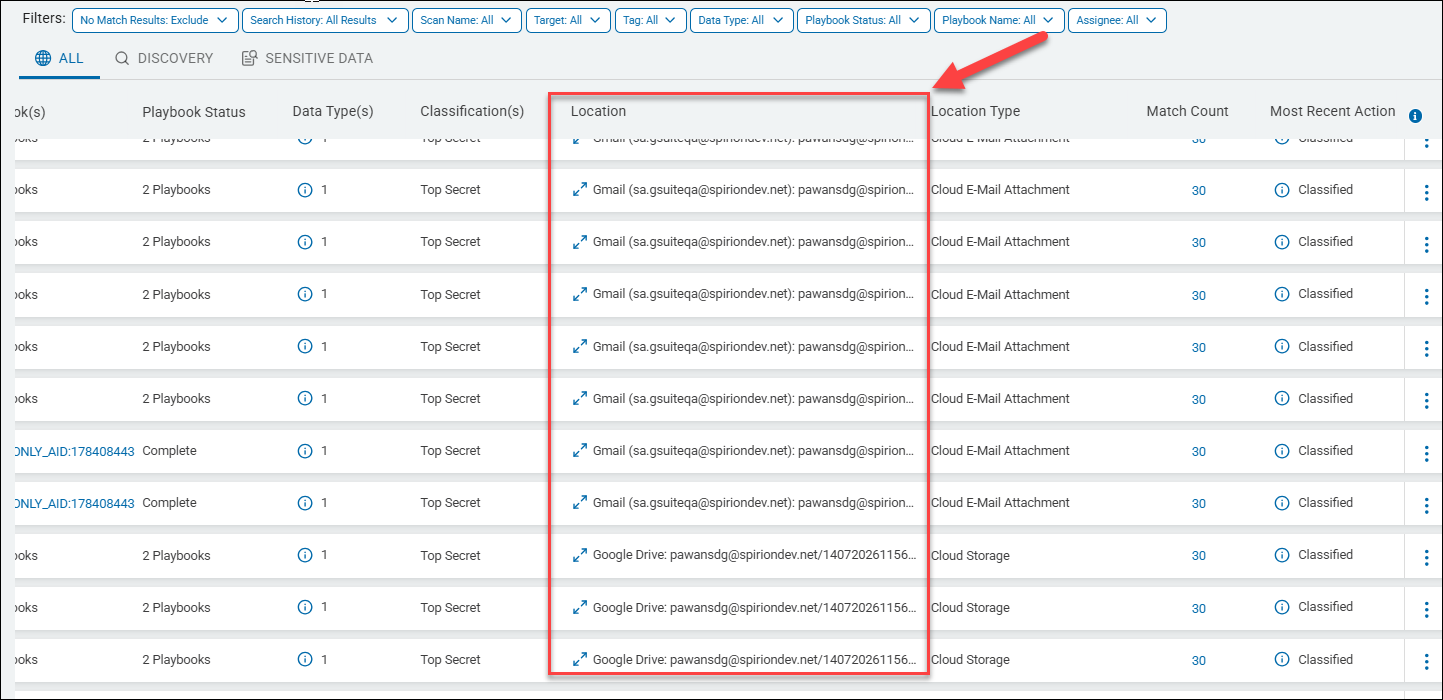
- Scan Results - Used on files/emails found in the scan results, after the scan completes
Scan Policy & Playbook Configuration
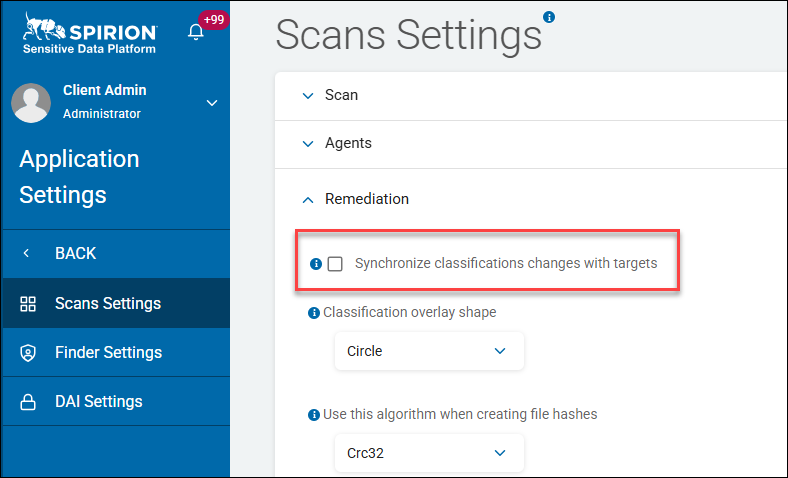
- Under Scan Settings (Settings > Application Settings > Scan Settings):
- Location: On the Scans Settings page under the Remediation section. This page controls global scan settings (individual scan setting are set in the scan wizard)
- The Setting: "Synchronize classifications changes with targets"
- Persistence Scope: When a user or automated playbook changes a file's classification (for example, marking a document as Confidential, Public, PII, or applying a protection Tag) within the Spirion Console, with this setting:
- Enabled: Spirion pushes and synchronizes those classification updates directly to the underlying files on the target storage locations or endpoints. It writes the classification into the file's native metadata
- Examples: Microsoft Office document properties, EXIF metadata, NTFS Alternate Data Streams, or cloud/SharePoint metadata columns
- Disabled: Classification changes made are captured only inside the Spirion Console database. The Target files, file metadata, and storage locations remain unchanged.
- In Automated Scan Playbooks / Workflows:
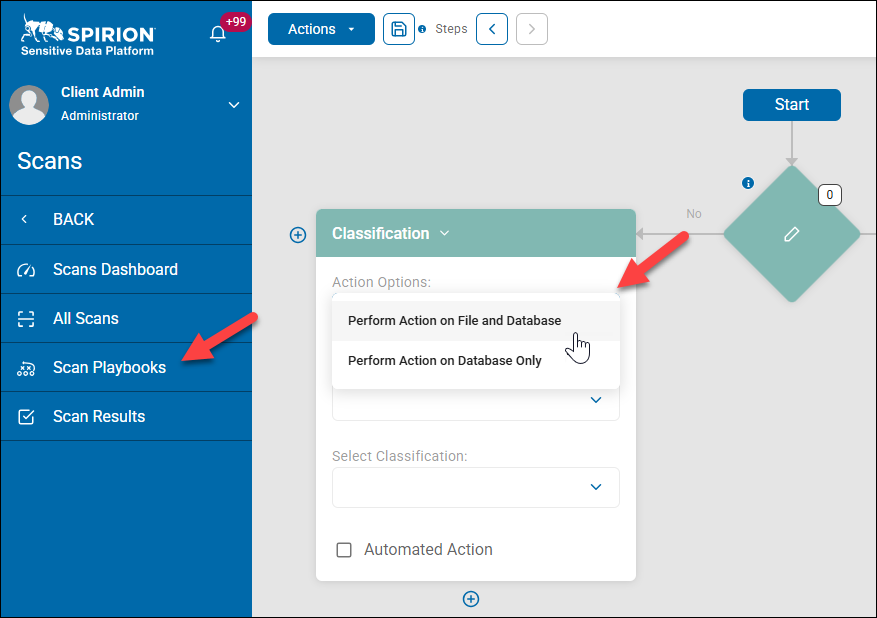
- From the left-side navigation select Scans > Scan Playbooks.
- Classification persistences can be set when you configure a Scan Playbook to use the Classification action upon sensitive data discovery (for example, If High Risk PII is found → Apply Classification). See the screenshot below.
- Under Action Options the action definition explicitly designates the persistence target:
- Perform Action on File and Database
- Perform Action on Database Only
WHEN is Classification Persistence Set/Applied?
Classification persistence is determined at configuration time and executed at specific runtime triggers:
1. Configuration Time (Pre-Scan Setup)
- Persistence rules are set prior to running scans during policy authoring.
- When the scan definition is dispatched, the persistence instruction is compiled into the scan task payload sent to the Agent.
2. Discovery & Inspection Runtime (Scan Execution)
- Match Evaluation: When the Search Agent scans a target item and AnyFind® / Regex detectors confirm a policy match:
- If Database-Only is set: The Agent records the match path, hash, and classification GUID into its local queue (
shipper_queue), leaving the target file untouched. - If Persistent Classification (File and Database) is set: The Agent immediately modifies the file's metadata (writing to Office custom XML, PDF XMP, or NTFS Alternate Data Streams) before reporting the result upstream.
- If Database-Only is set: The Agent records the match path, hash, and classification GUID into its local queue (
3. Post-Scan Triage / Manual Classification Action
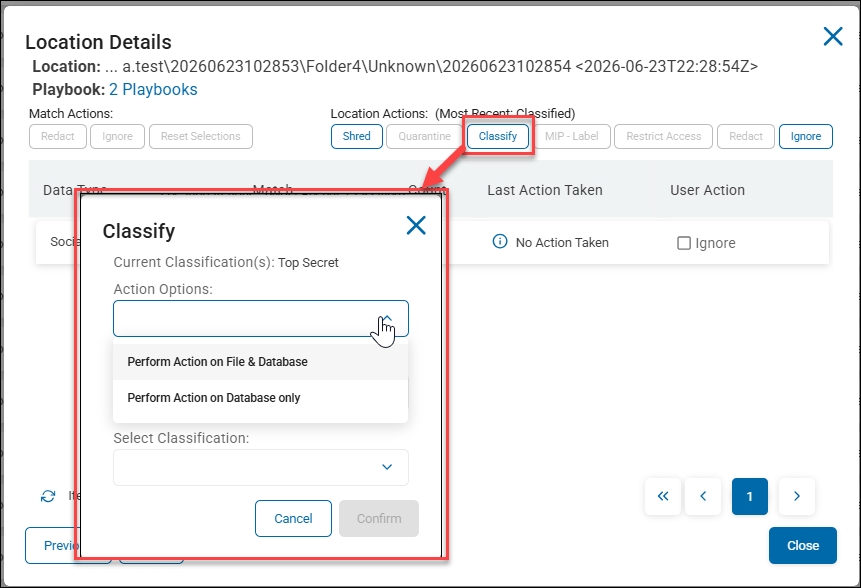
- When an administrator reviews discovered matches on the Scan Results page, they can open a scan location from the table to view Location Details (below).
- From the "Location Details" pop-up window, under Location Actions, selecting Classify opens the Classify pop-up window where the user can select a classification persistence from the drop-down menu to write persistent tags to the selected file or email.