
What is the Spirion Sensitive Data Platform v13.6+ end-to-end data pipeline?
Below is the complete architecture diagram and operational documentation for the Spirion Sensitive Data Platform (SDP) v13.6+ end-to-end data pipeline.
📐 End-to-End Data Pipeline Architecture Diagram
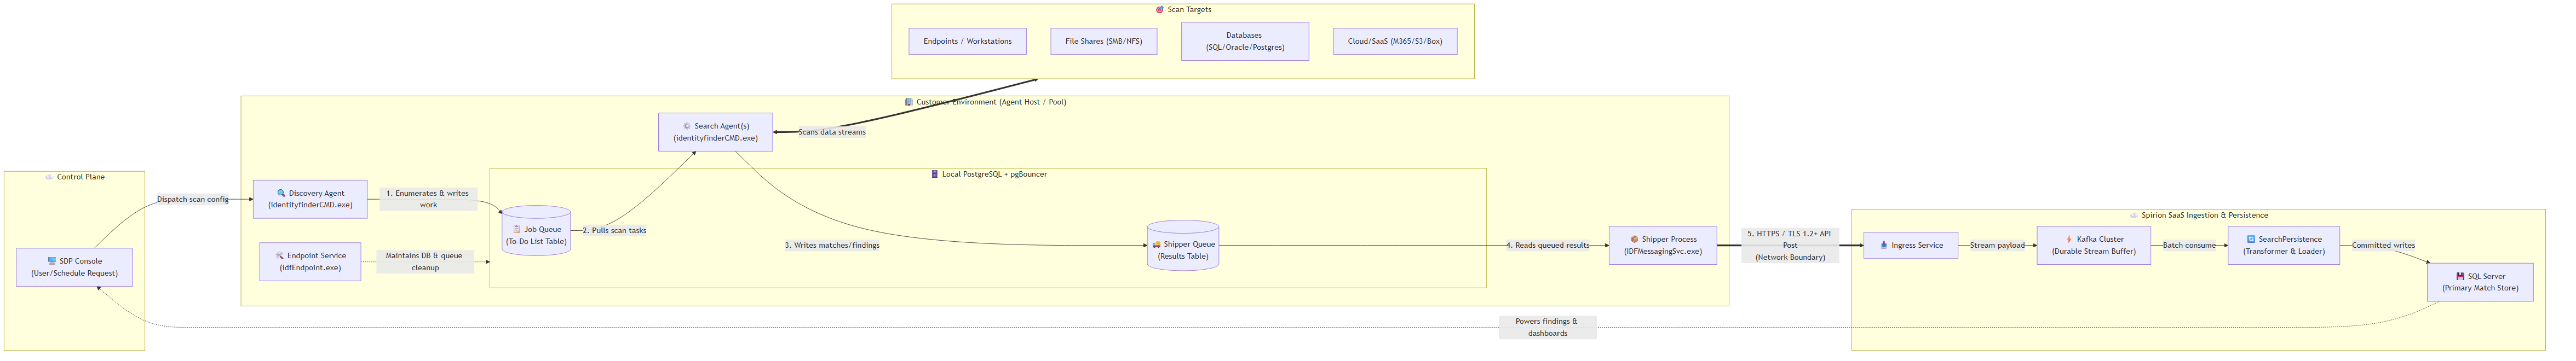
🔄 Step-by-Step Data Journey
The v13.6 pipeline is built as a chain of decoupled stages so temporary issues (network drops, proxy timeouts, or machine reboots) never result in lost work or restarted scans:
Stage 1: Discovery & Job Creation (Client-Side)
- Discovery Agent (
identityfinderCMD.exe): Triggered by the Console or local schedule, the Discovery Agent connects to the target repository (e.g., file share, database schema, mailbox) and enumerates all items to search. - Job Queue (
PostgreSQL): The Discovery Agent converts the target items into granular units of work (rows) and inserts them into the local PostgreSQLJob Queuetable.
Stage 2: Execution & Inspection (Client-Side)
- Search Agent (
identityfinderCMD.exe): One or more worker threads pull "Pending" jobs from the local Job Queue, changing row statuses to "Processing". - Data Inspection: Workers stream content across native connectors (ODBC, Graph API, S3 SDK, SMB) and run regex, dictionary matching, validation algorithms, and OCR directly in local memory.
Stage 3: Local Buffering & Result Queuing (Client-Side)
- Shipper Queue (
PostgreSQL): Discovered matches and metadata are written as durable rows into the localShipper Queuetable. - Separation of Concerns: Because search results are buffered locally first, scanning can continue at full speed even if external internet connectivity is degraded.
Stage 4: Crossing the Network Boundary
- Shipper Service (
IDFMessagingSvc.exe): Continuously monitors the Shipper Queue table, bundles pending results into encrypted payloads, and transmits them over HTTPS (TLS 1.2+) to the cloud Ingress endpoint. - Resilience: If the network is unavailable, rows remain in the local PostgreSQL table until connectivity is re-established.
Stage 5: High-Throughput Cloud Ingestion (Server-Side)
- Ingress Service: Authenticates the agent token and accepts incoming result payloads.
- Kafka Cluster: Ingests raw findings into distributed, fault-tolerant topics. Kafka acts as an elastic shock absorber during massive enterprise scan bursts.
- SearchPersistence: Consumes batches from Kafka, validates schema integrity, and maps finding metadata into the relational schema.
- SQL Server Database: Commits the final records to long-term storage, immediately updating Console dashboards, match counts, and Playbook triggers.
🧩 Core Process & Service Directory (v13.6+)
Process / Component | Host Location | Function / Description |
|---|---|---|
Local PostgreSQL | Client Endpoint | Stores local |
pgBouncer | Client Endpoint | Connection pooler acting as a "traffic cop" to minimize RAM and CPU overhead for local DB connections. |
idfEndpoint.exe (EPS) | Client Endpoint | Endpoint supervisor service; ensures schema initialization, agent registration, health heartbeats, and queue maintenance/retries. |
identityfinderCMD.exe (IDF) | Client Endpoint | Search engine; executes discovery enumeration, content parsing, detector algorithms, and result generation. |
IDFMessagingSvc.exe (IFS) | Client Endpoint | Shipper service; reads rows from the local Shipper Queue and posts them to cloud Ingress. |
Ingress Service | SaaS / Cloud | Edge API gateway receiving shipped result payloads from Agent fleets. |
Kafka Cluster | SaaS / Cloud | Distributed streaming queue buffering raw incoming findings between Ingress and SearchPersistence. |
SearchPersistence | SaaS / Cloud | Microservice that transforms buffered Kafka messages and writes structured findings into SQL Server. |
SQL Server | SaaS / Cloud | Central relational database storing scan records, tenant configurations, and compliance match data. |